MisoTTS on Apple Silicon: Local TTS Works, But Not in Real Time
A practical MisoTTS MLX run on local hardware: five voice samples, load time, generation speed, memory usage, audio outputs, and playback-ready blog samples.
 8bit blogs
Articles filed under this topic.
A practical MisoTTS MLX run on local hardware: five voice samples, load time, generation speed, memory usage, audio outputs, and playback-ready blog samples.
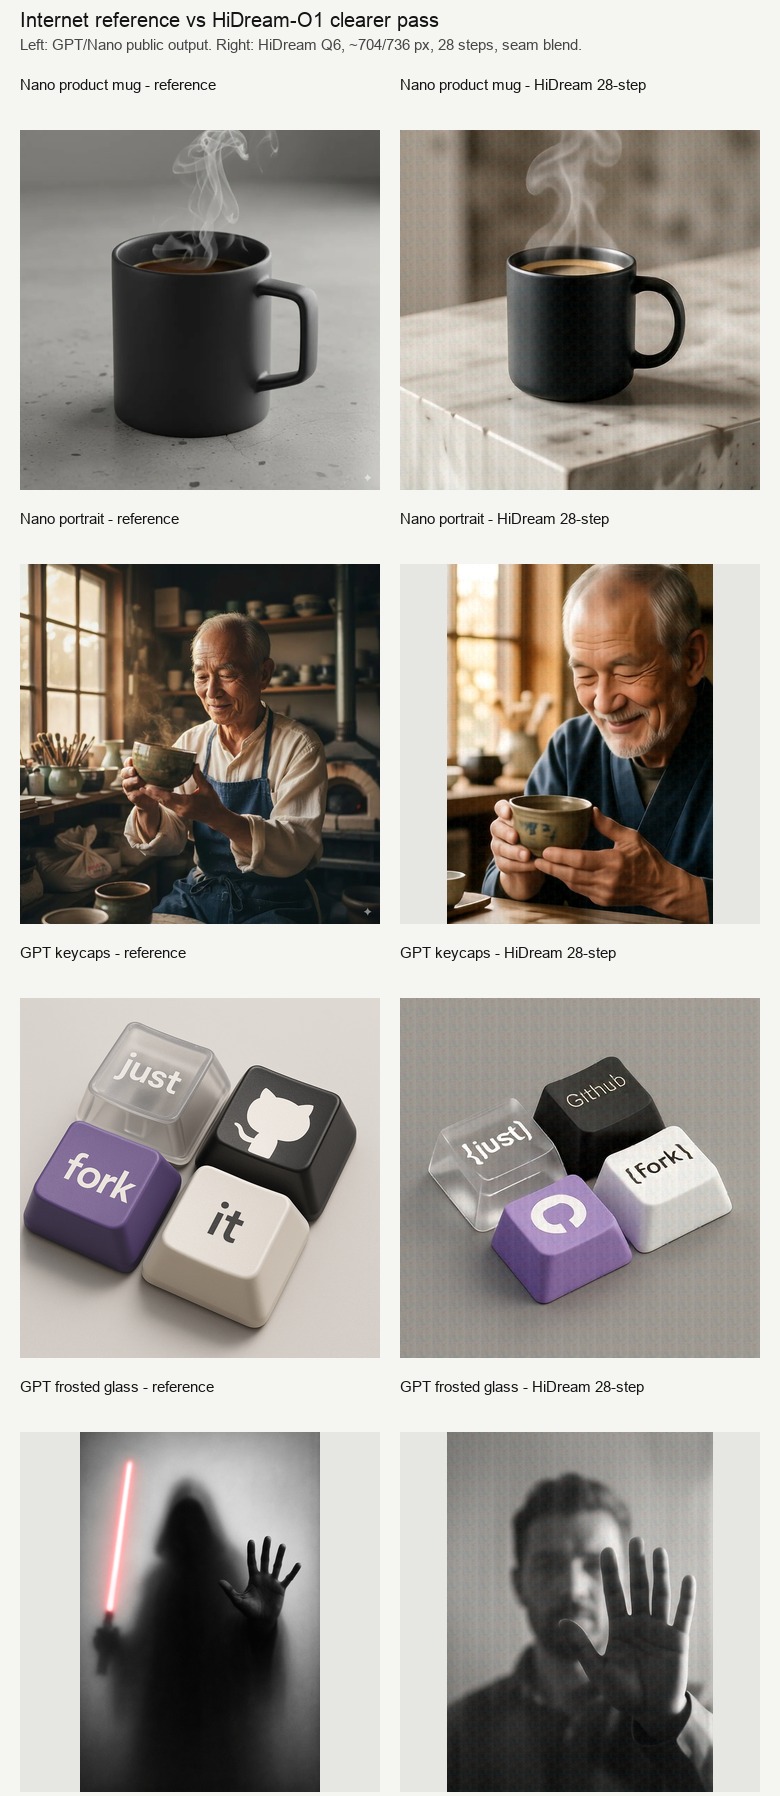
Same prompts, public GPT/Nano references, local HiDream-O1 generations: why the first images looked blurry, what fixed them, and where hosted models still win.
I tried five public benchmark-style prompts on HiDream-I1, compared where it behaves like the public GPT image examples, and where it clearly still struggles.
Where Am I? This is the second part of our Transformer series blog, where we will deep dive into a topic called positional embedding. In this part, we’ll see what PE is and the types of PEs. Background Classical NL...
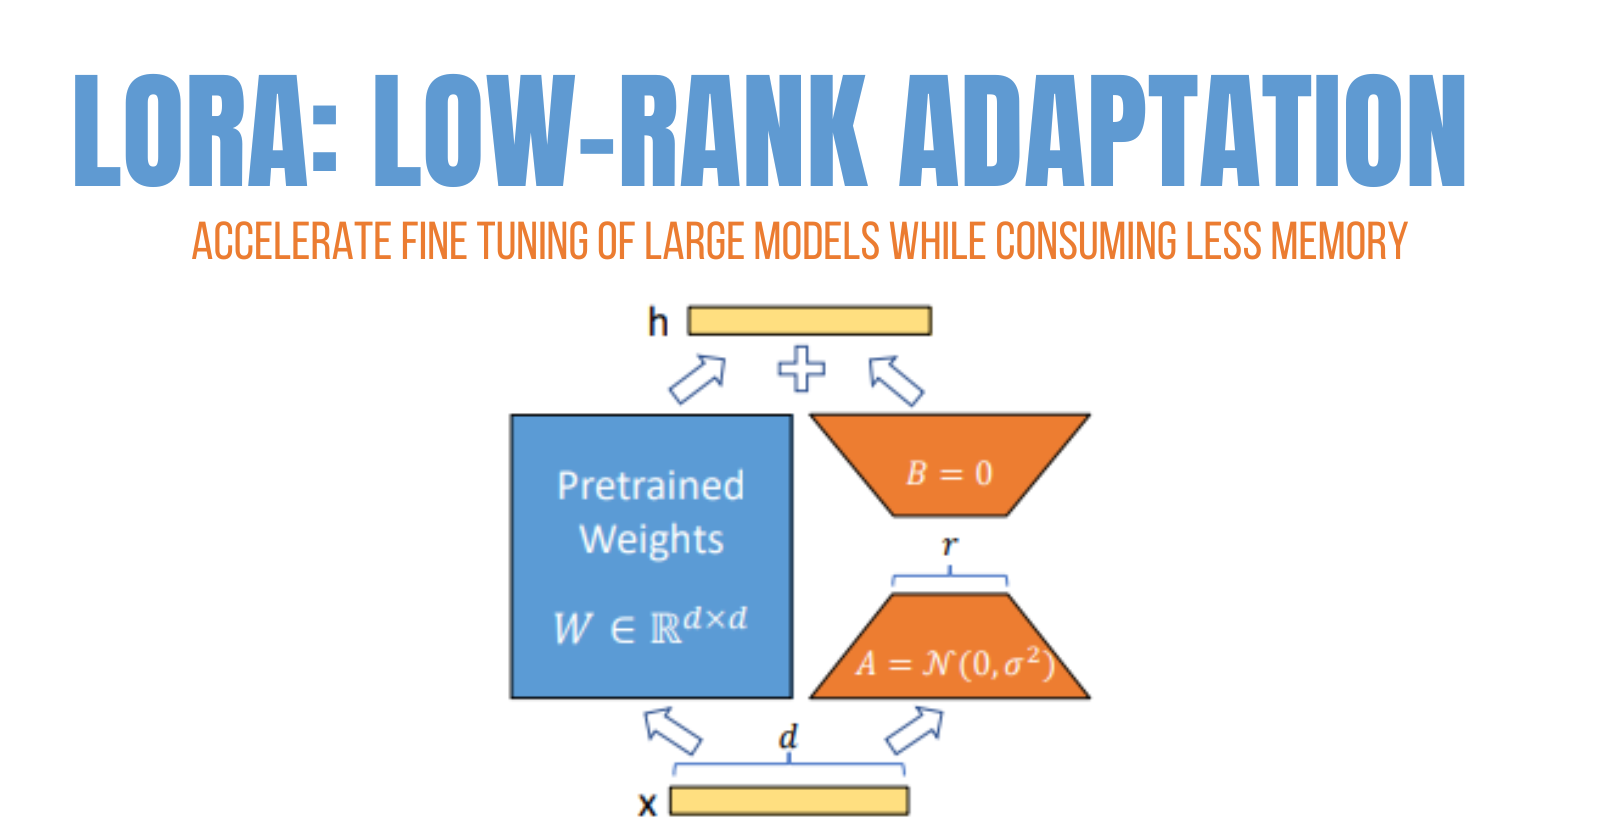
In the last part of Compression of NN[1], we delved into methods for reducing the memory footprint of large ML models, in this part let's look into how to fine-tune these large models in consumer grade resources with...
In the realm of artistry, where creativity and imagination intertwine, a captivating scene often begins as a humble sketch on paper. Though fascinating in their monochrome simplicity, these lines and contours often le...
I know I'm late for the party. It's been a long time since the diffusion models have been introduced. There have been massive improvements in image generation since I have known image generation with ML, from GANs to...