Positional Encoding
Where Am I? This is the second part of our Transformer series blog, where we will deep dive into a topic called positional embedding. In this part, we’ll see what PE is and the types of PEs. Background Classical NL...
 8bit blogs
Articles filed under this topic.
Where Am I? This is the second part of our Transformer series blog, where we will deep dive into a topic called positional embedding. In this part, we’ll see what PE is and the types of PEs. Background Classical NL...
“This will be a small experiment”. My thoughts as I started working on it a month ago. It is a simple concept of caching previous results for future calculations, similar to dynamic programming in DSA. I could not hav...
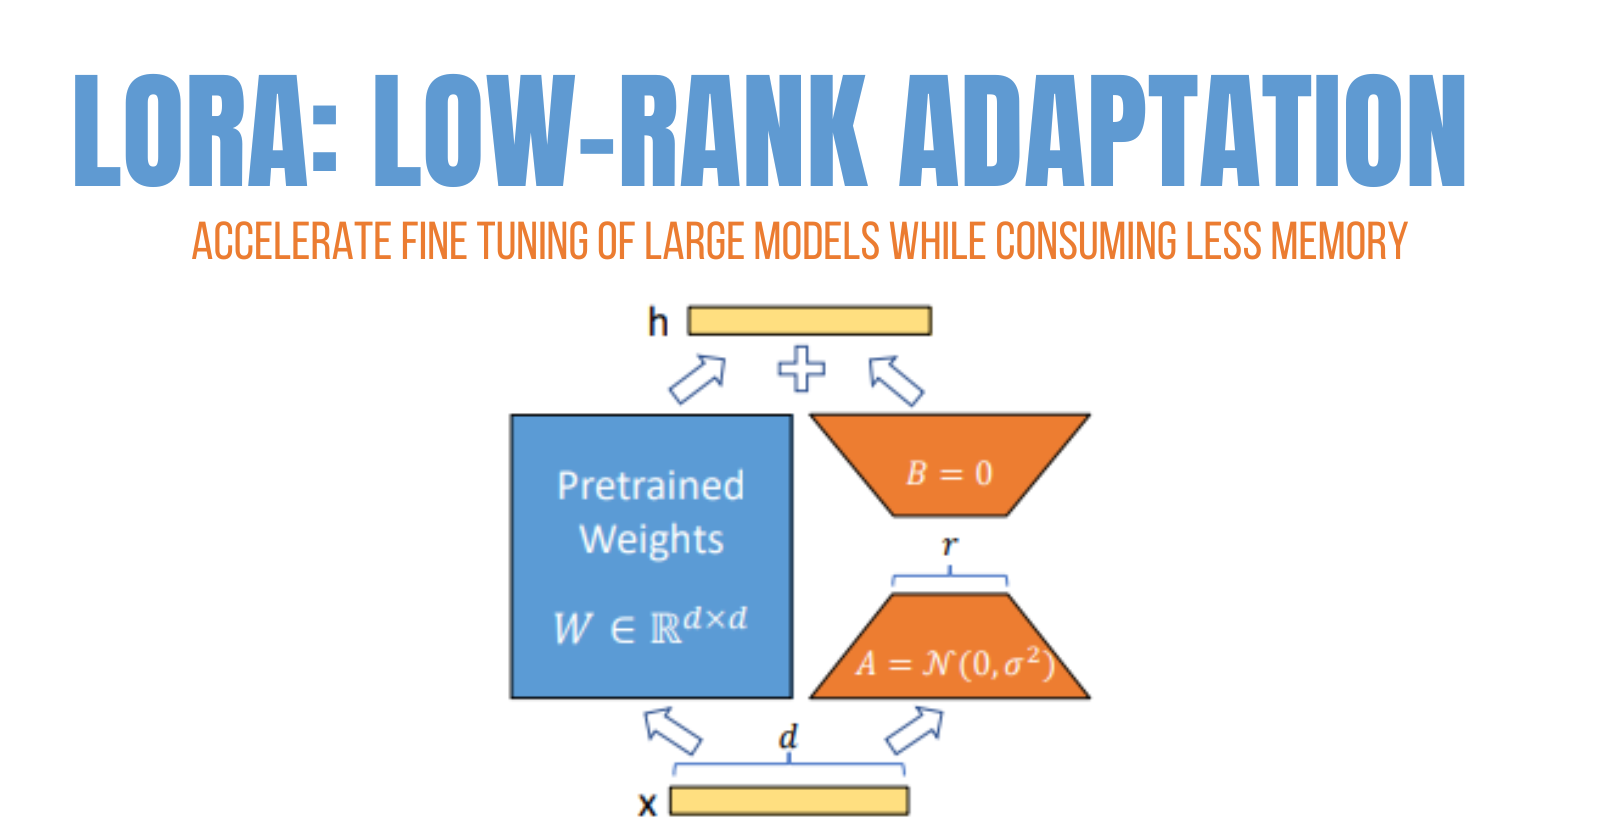
In the last part of Compression of NN[1], we delved into methods for reducing the memory footprint of large ML models, in this part let's look into how to fine-tune these large models in consumer grade resources with...